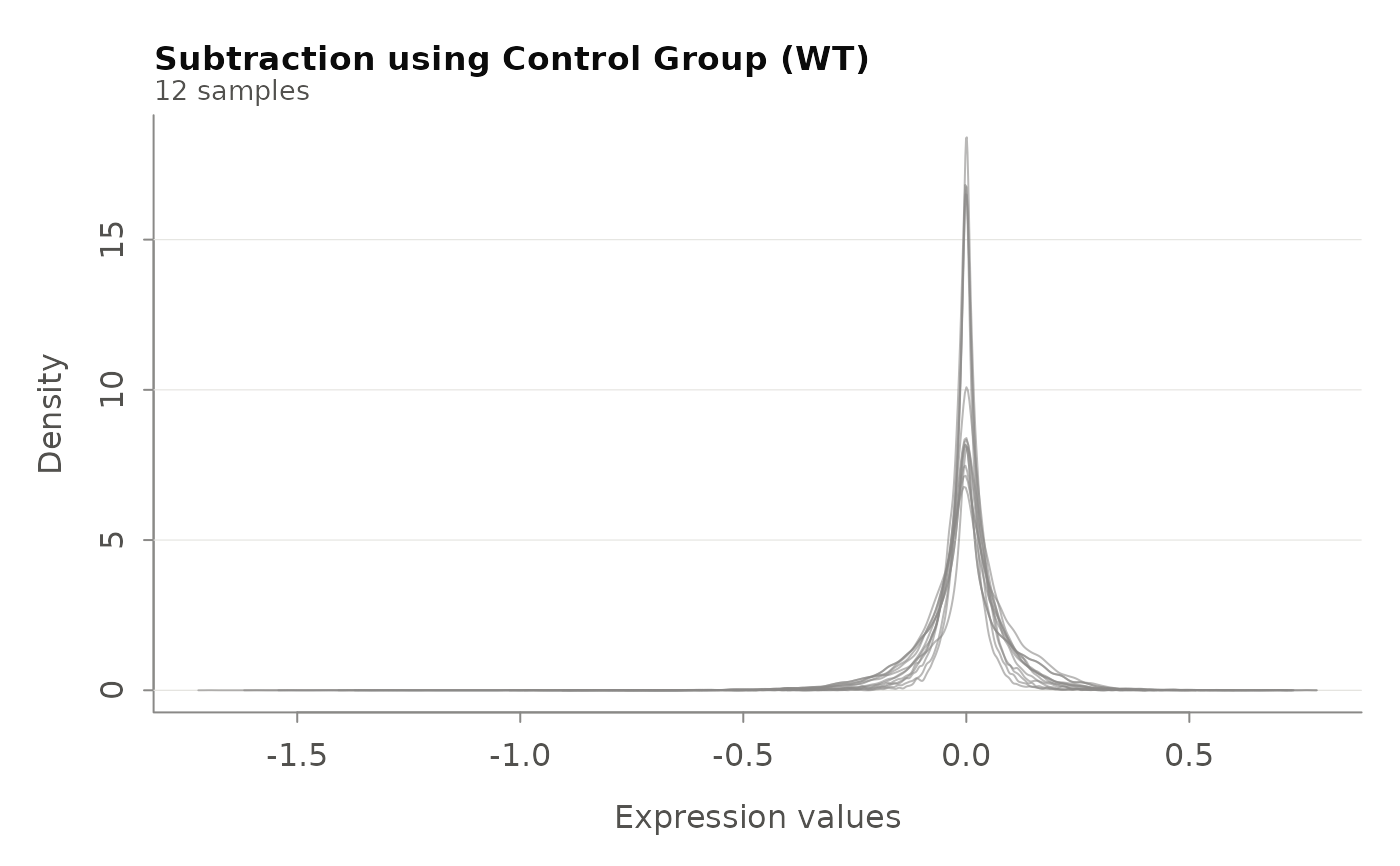
This function performs a complete preprocessing pipeline for transcriptomic age analysis, including gene filtering, normalization, transformation, scaling, control subtraction, and gene ID conversion. It returns multiple versions of the processed data suitable for different analysis approaches.
Usage
tAge_preprocessing(
  eset,
  species = "mouse",
  gene_mapping_type = "auto",
  verbose = TRUE,
  control_group_column = NULL,
  control_group_label = NULL,
  count_threshold = 10,
  percent_threshold = 20,
  split_by = NULL
)
Arguments
- eset
An ExpressionSet object containing raw integer counts (no NA, no negative or non-integer values; normalised data are refused).
- species
Species of the samples: "mouse", "rat", "human" or "monkey" (see
tage_species). Default is "mouse".- gene_mapping_type
Identifier type of the row names: "Ensembl", "Gene.Symbol", "Entrez" or "auto" (default, detected from the gene table; see
map_genes).- verbose
Logical indicating whether to print progress messages. Default is TRUE.
- control_group_column
Character string specifying the column name in phenoData that contains control group labels. Default is NULL.
- control_group_label
Character string specifying the label for control samples. Default is NULL. With
split_by, the controls of each stratum are its reference; a stratum without controls is centred on all of its samples, with a warning. A column that does not exist, or a label that no sample carries, is an error.- count_threshold
Numeric threshold for minimum expression count in gene filtering. Default is 10.
- percent_threshold
Numeric threshold for minimum percentage of samples that must have expression above count_threshold. Default is 20.
- split_by
Character or NULL. Column of the phenoData whose levels (tissues, datasets, cell types) are preprocessed separately. Default NULL.
Value
A list containing six processed ExpressionSet objects:
- RLE_normalized
RLE-normalized data
- log_transformed
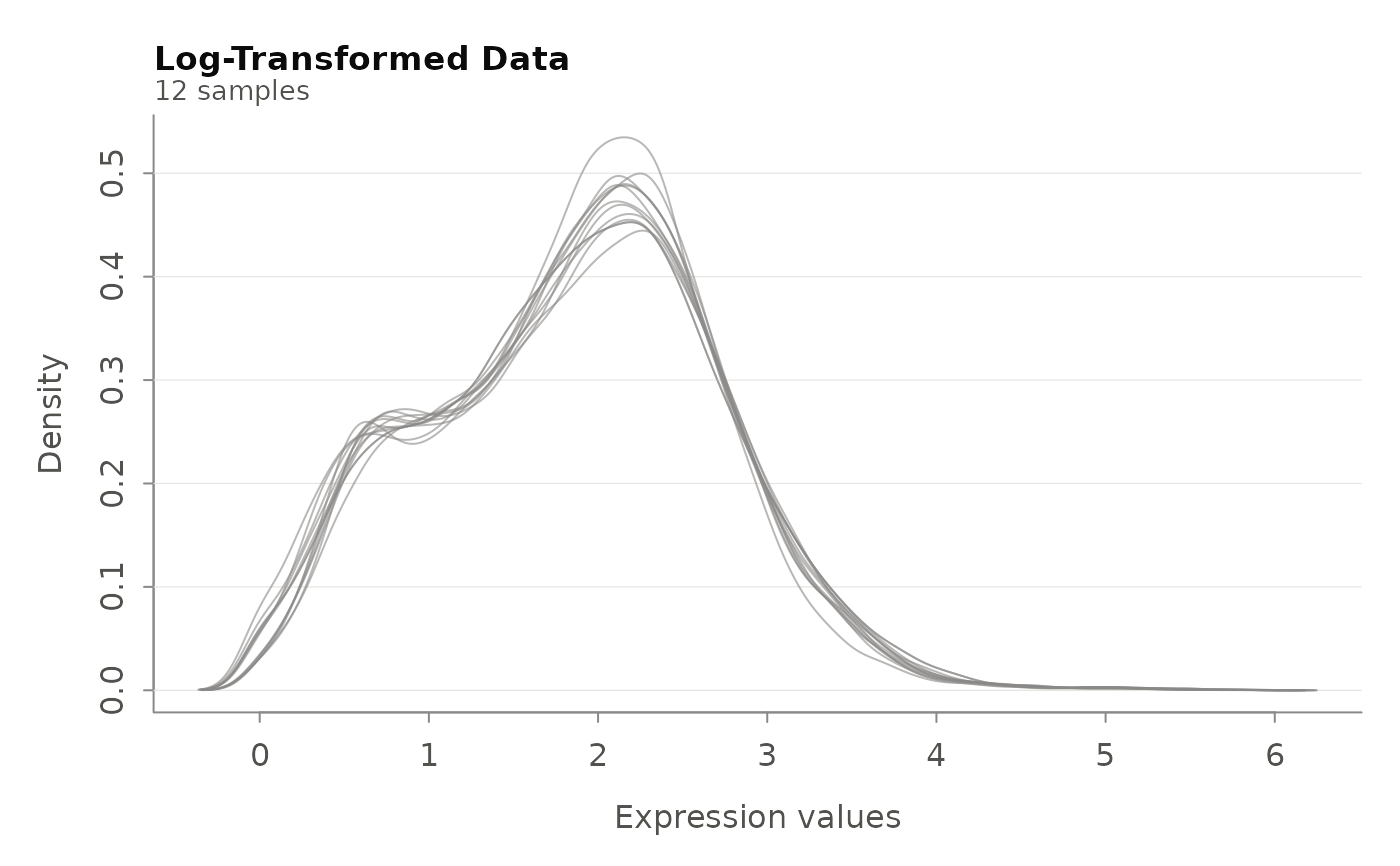
Log-transformed data
- scaled
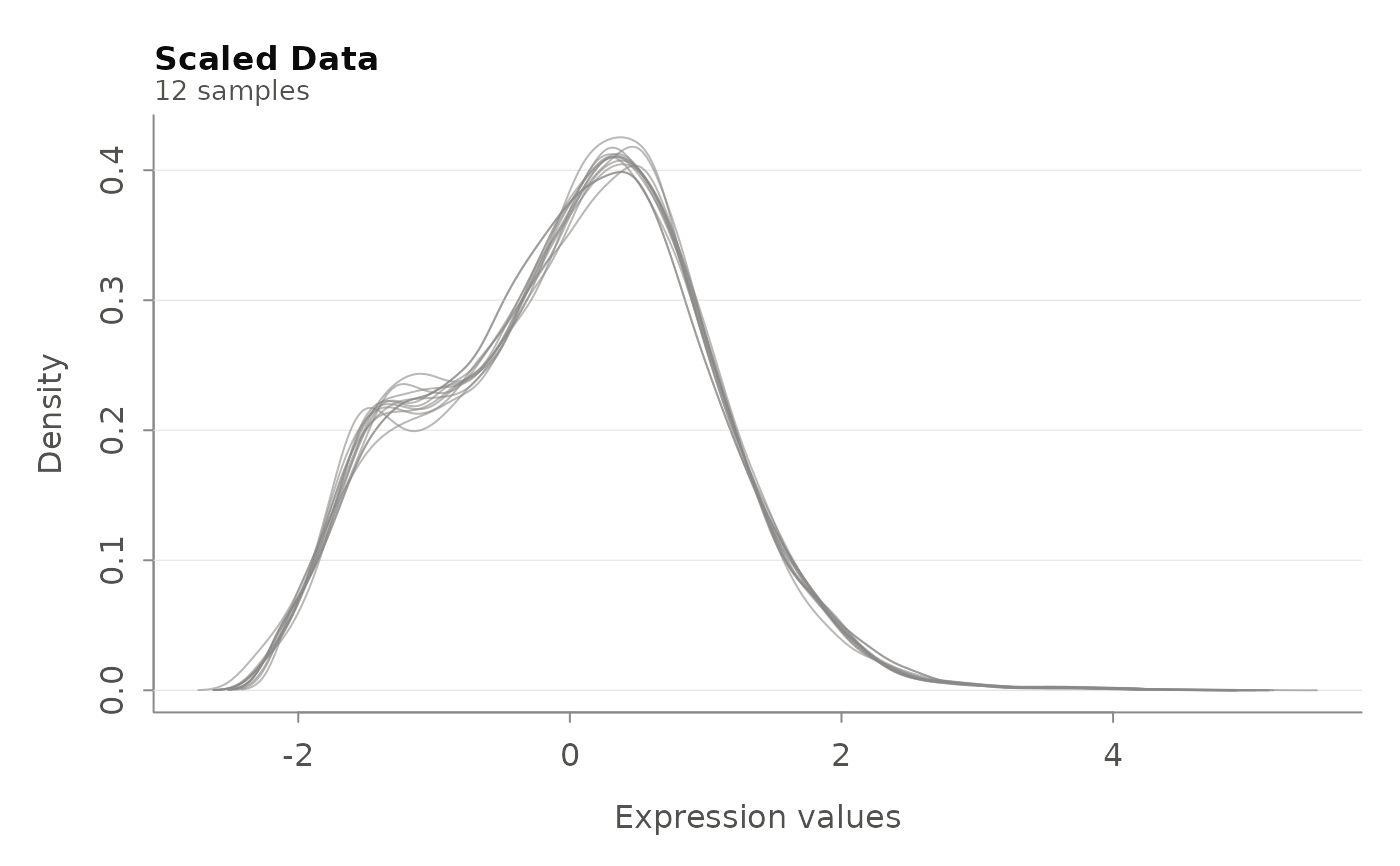
Scaled data with gene ID conversion
- scaled_diff
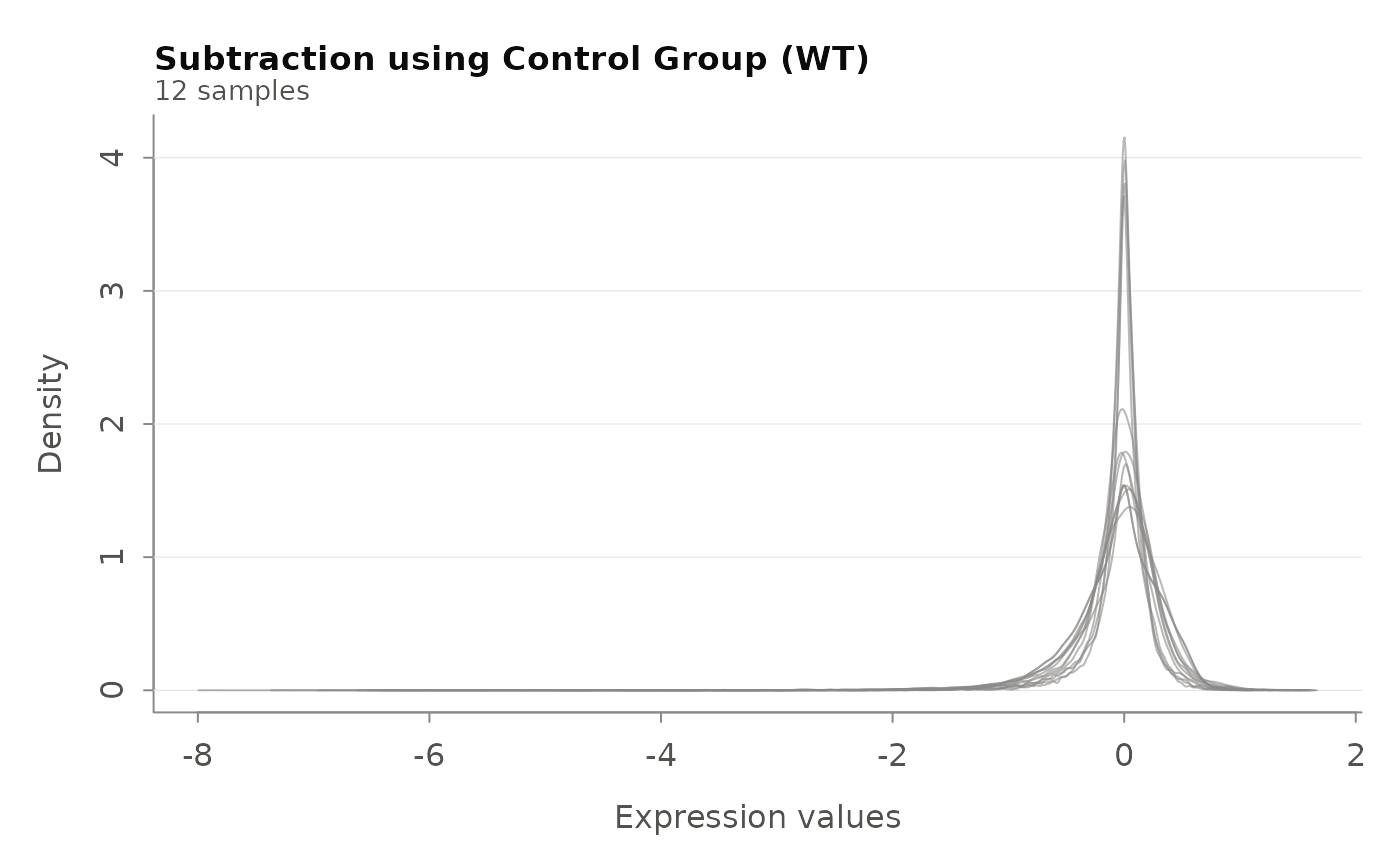
Scaled data with control subtraction and gene ID conversion
- yugene
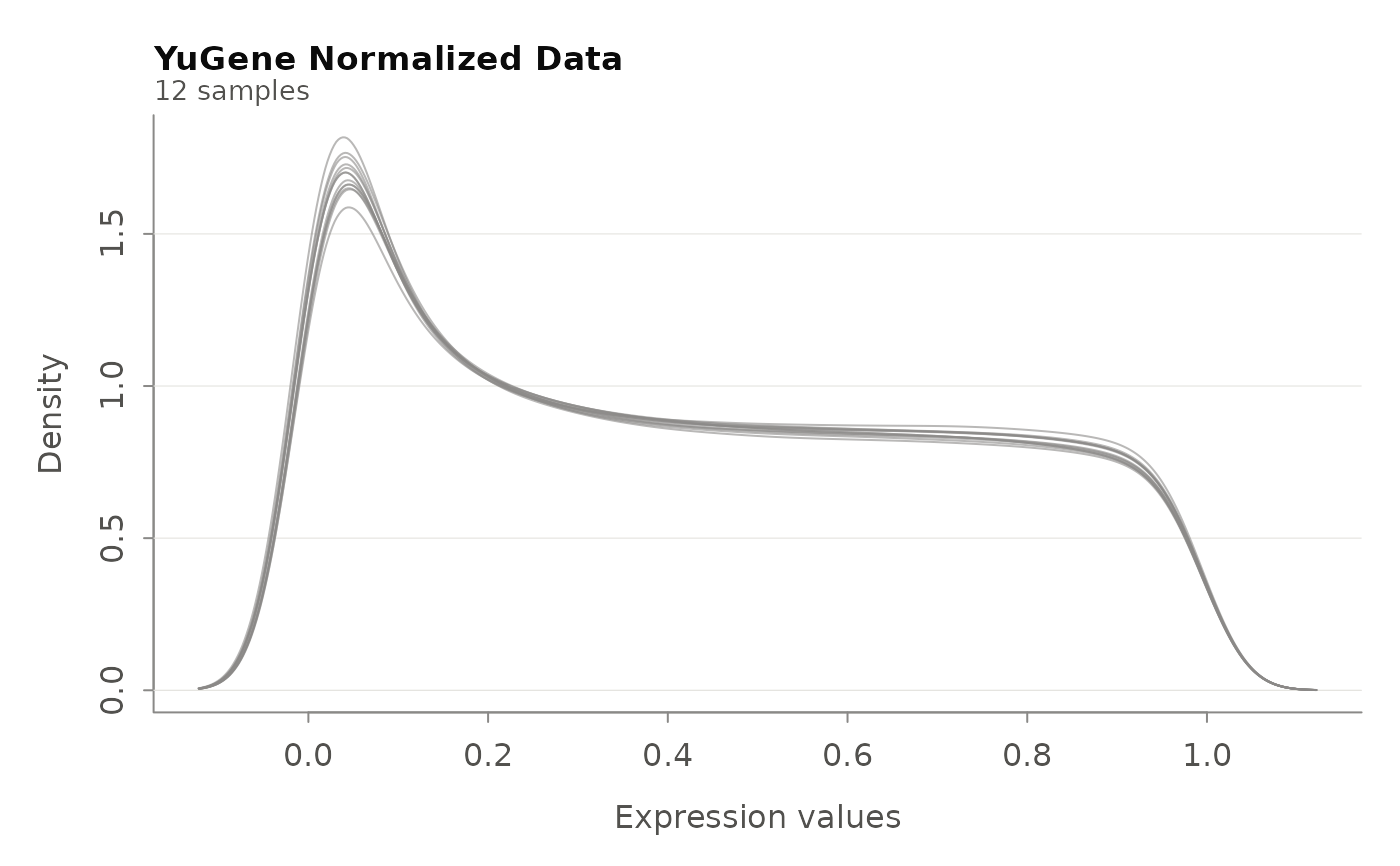
YuGene-normalized data with gene ID conversion
- yugene_diff
YuGene-normalized data with control subtraction and gene ID conversion
Details
The clocks were trained on expression centred within each dataset and
tissue against matched controls, and that is how they should be applied:
with several tissues (or datasets, cell types) in one ExpressionSet, pass
split_by so that gene filtering, normalisation and reference
centring all happen within each stratum, and the results are combined
afterwards. Without split_by the whole object is one stratum.
The species is recorded in every returned ExpressionSet, so
predict_tAge does not need it again.
Examples
# Load example data
expr_data <- load_example_expression_data()
meta_data <- load_example_metadata()
eset <- make_ExpressionSet(expr_data, meta_data)
#> ✓ ExpressionSet created successfully
#> - Number of genes: 57010
#> - Number of samples: 24
 # Run complete preprocessing pipeline
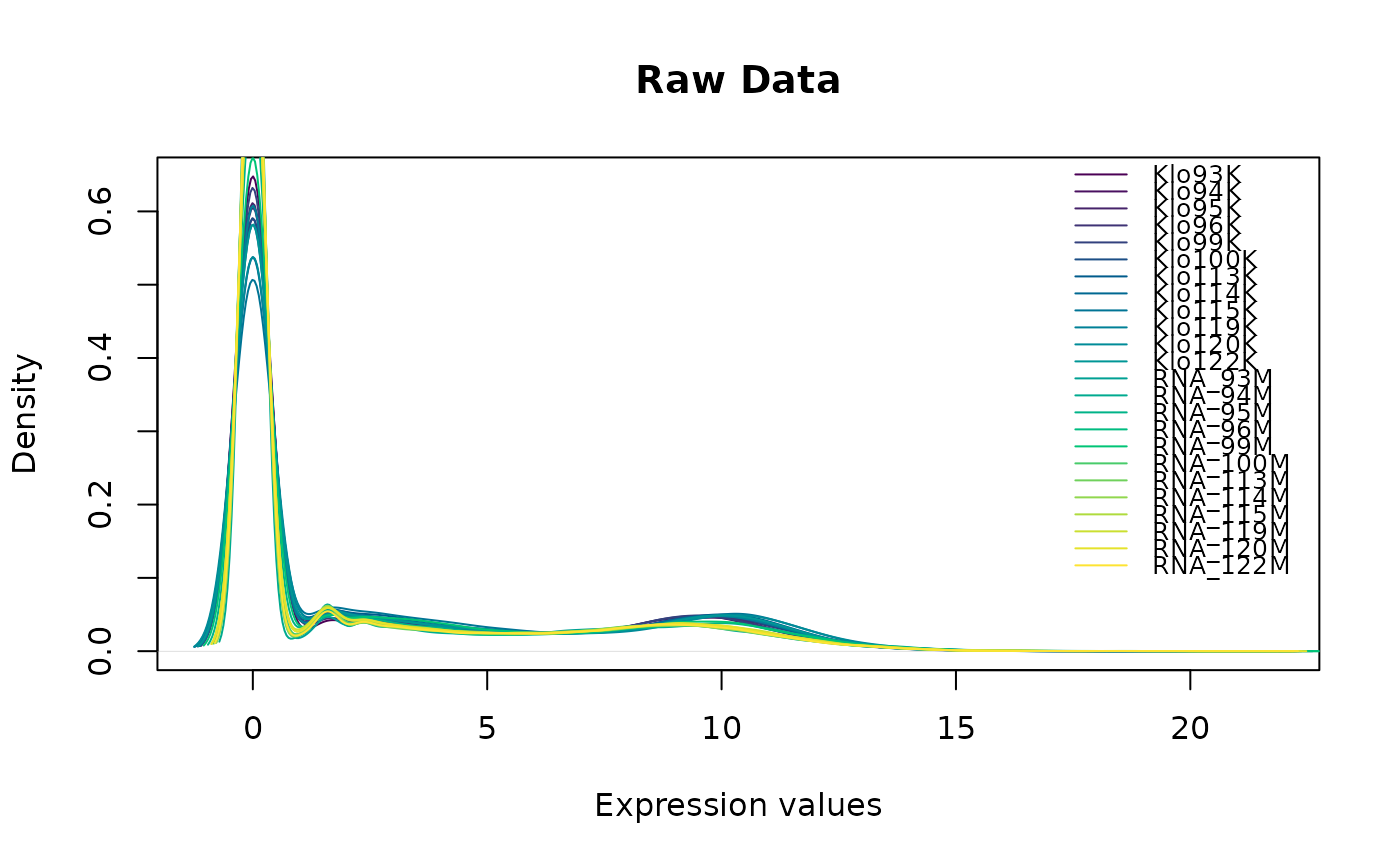
processed_data <- tAge_preprocessing(eset, species = "mouse")
#> ✓ Gene filtering completed
#> - Number of genes before filtering: 57010
#> - Number of genes after filtering: 19550
#> - Percentage of genes retained: 34.3 %
#> ✓ Gene identifiers: Ensembl (15996 of 19550 row names found in the mouse gene table)
#> calcNormFactors has been renamed to normLibSizes
#> ✓ RLE normalization completed
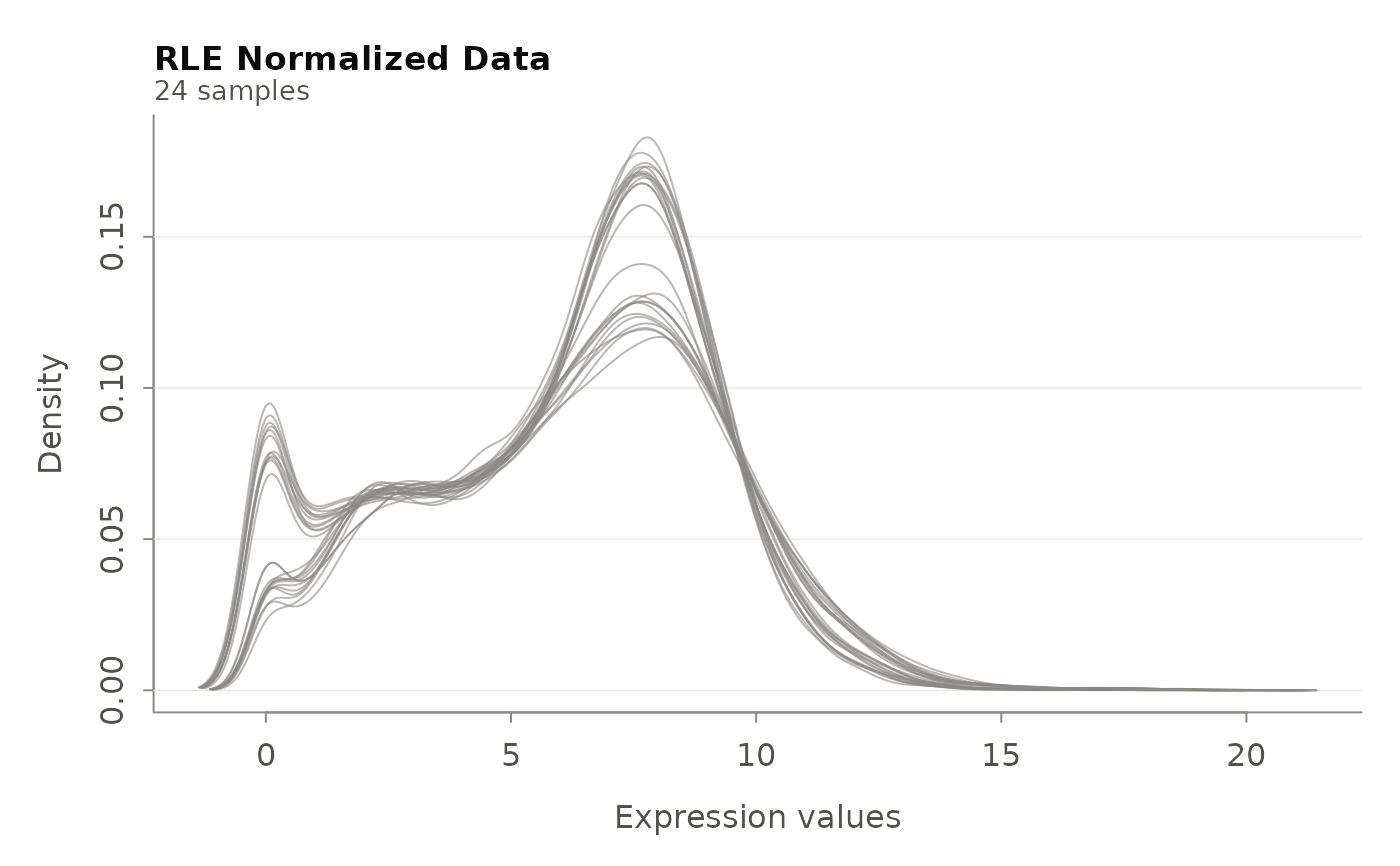 #> ✓ Log transformation completed
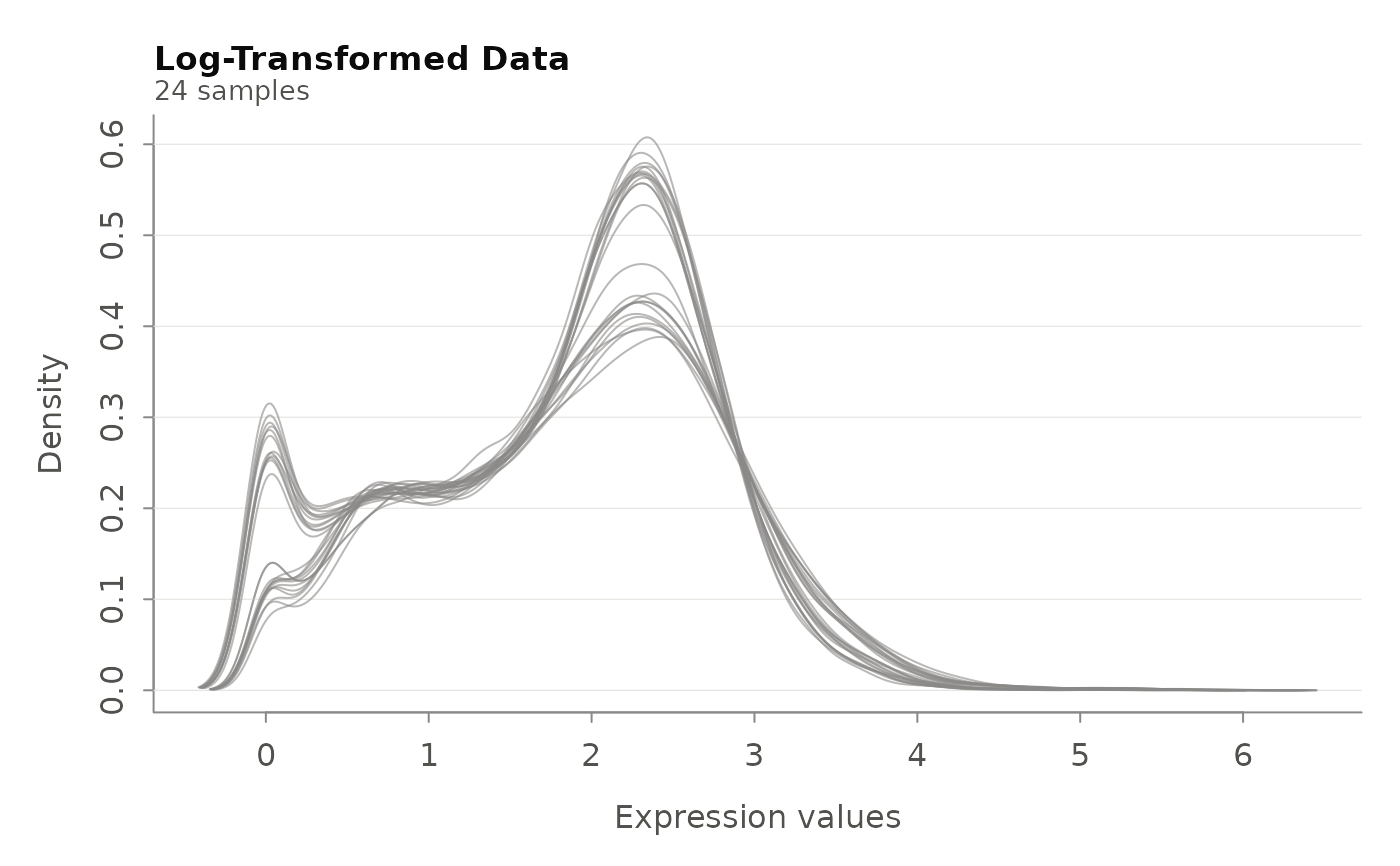 #> ✓ Scaling completed
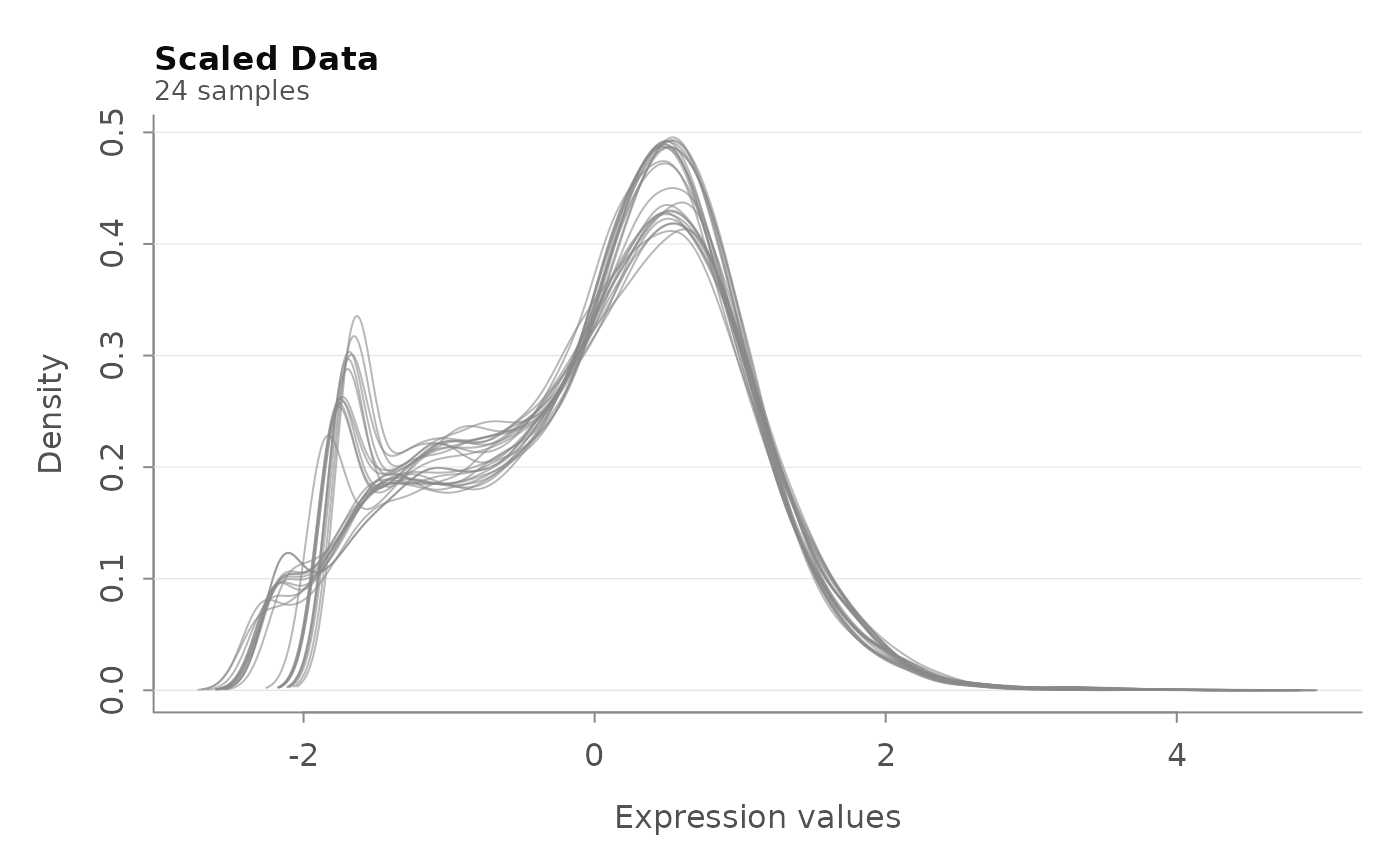 #> ✓ YuGene normalization completed
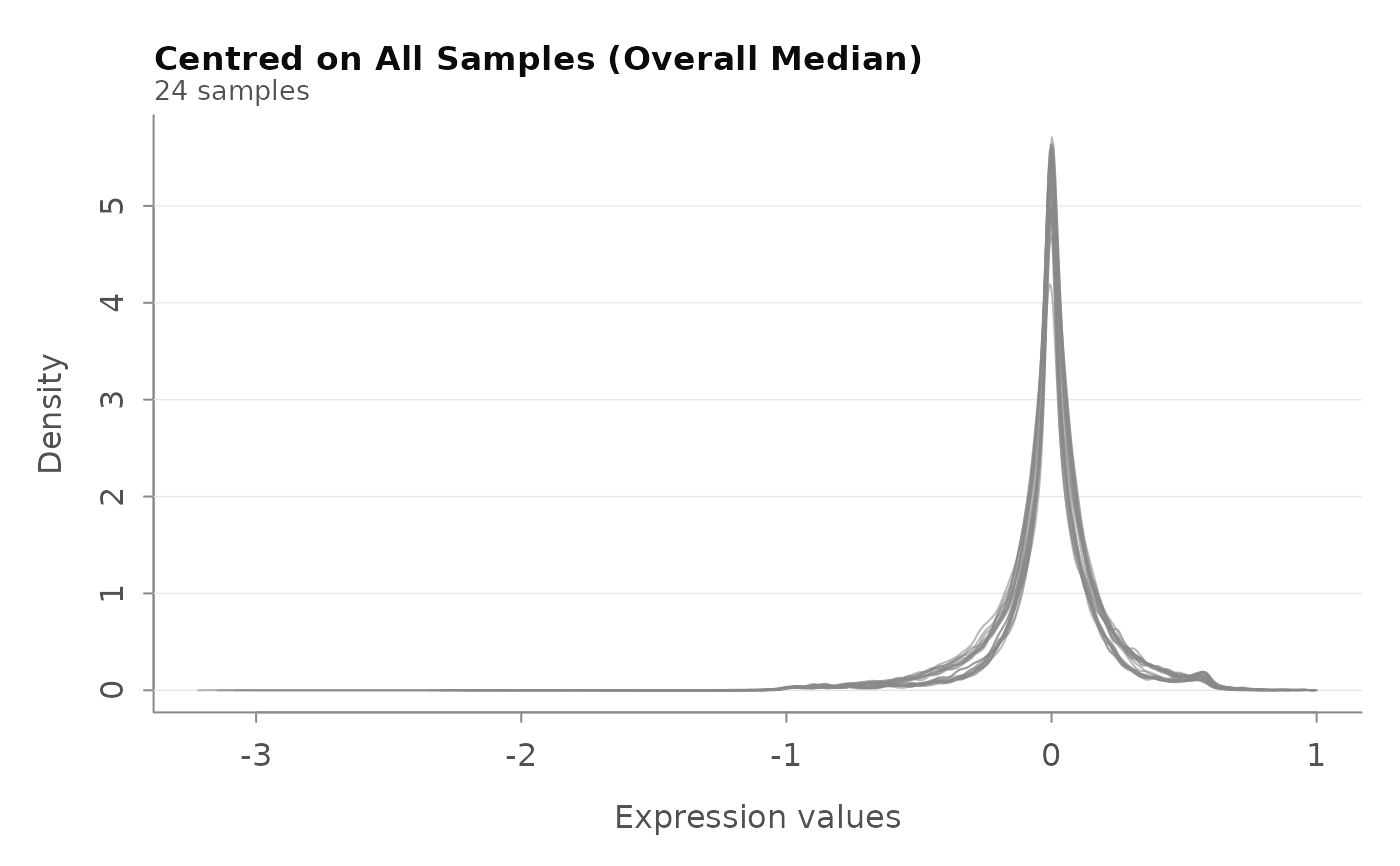
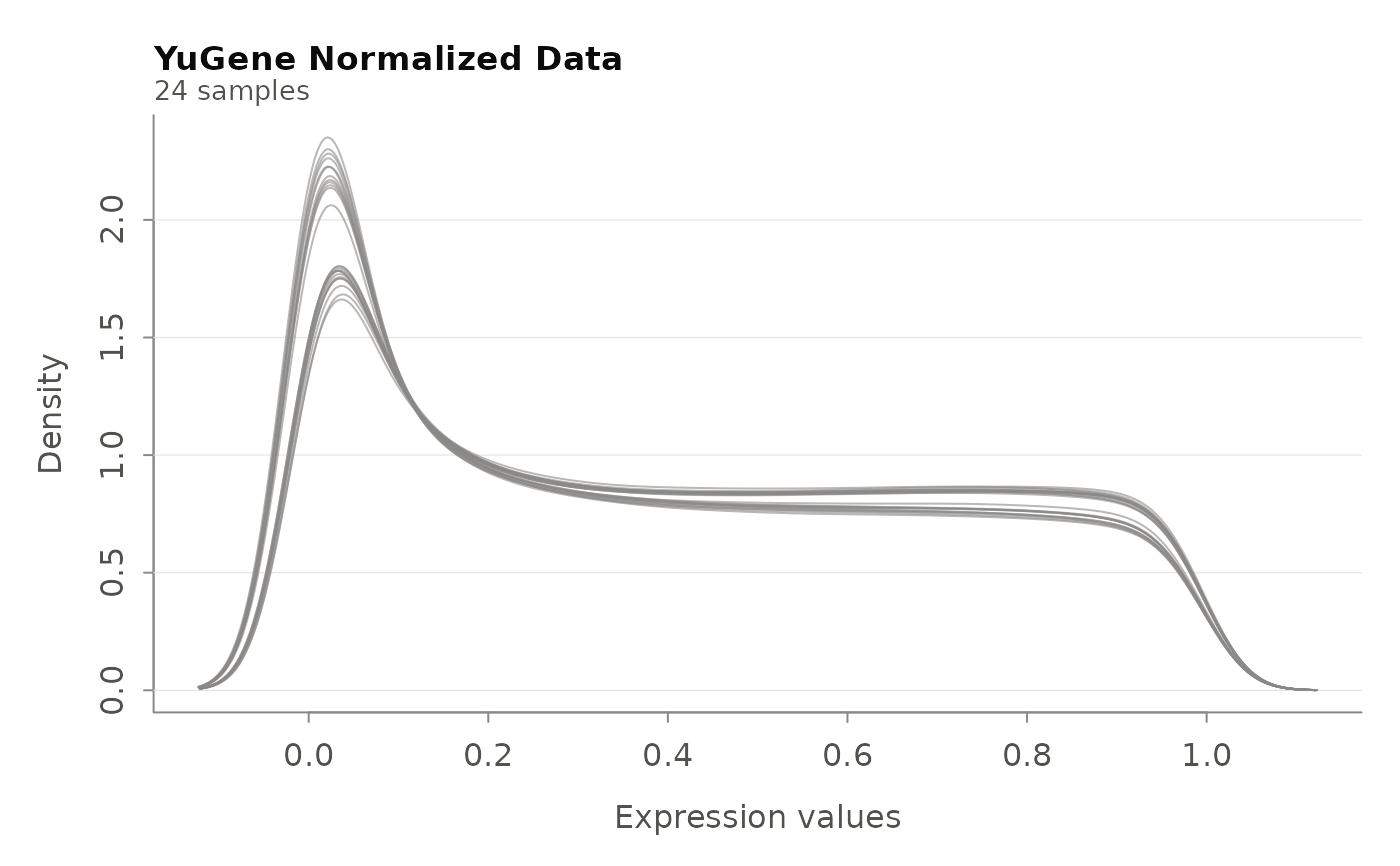 #> ✓ Centring on all samples (overall per-gene median; no reference group specified).
#> Warning: NaNs produced
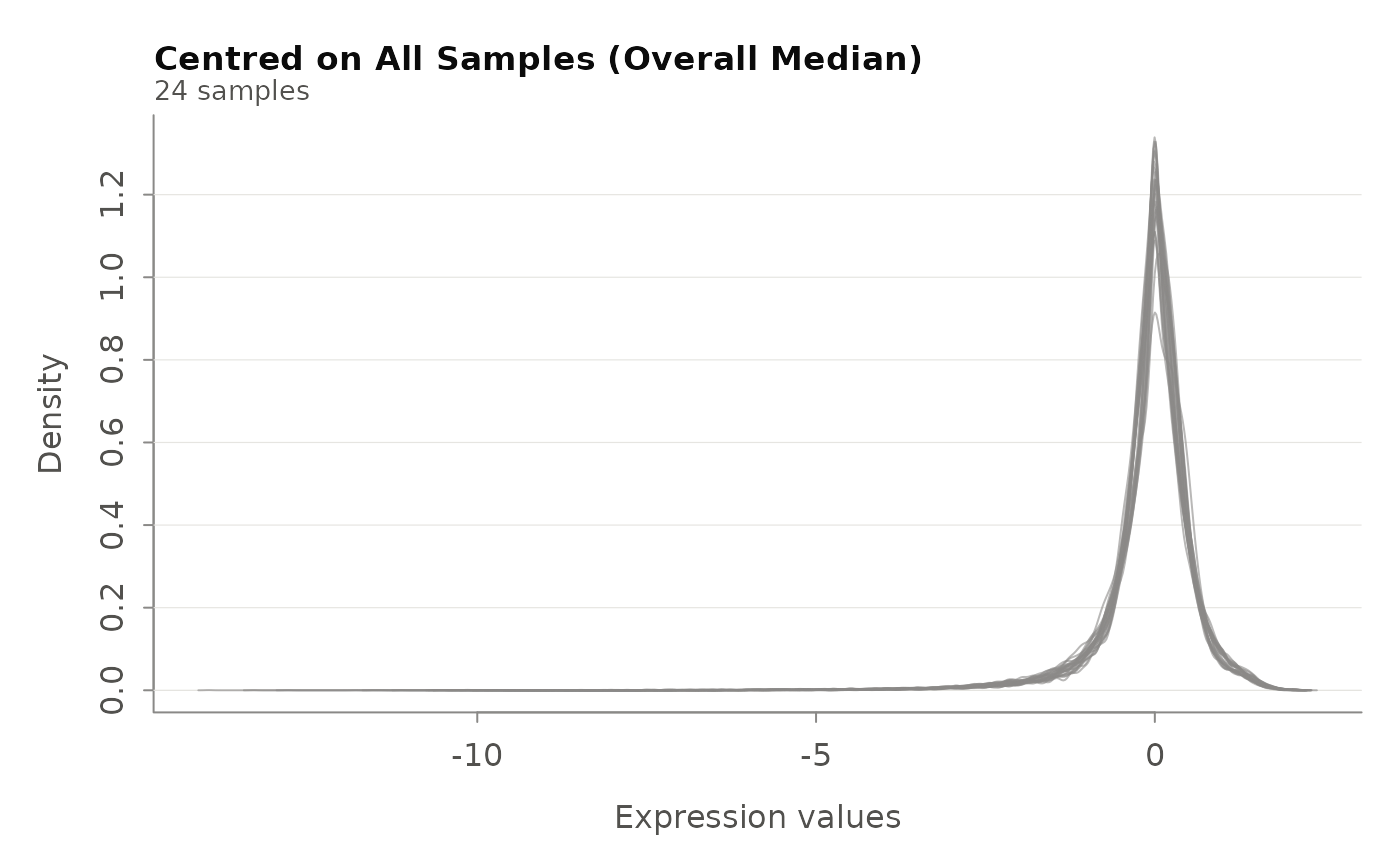 #> ✓ Centring on all samples (overall per-gene median; no reference group specified).
 # Two tissues: filter, normalise and centre each on its own wild-type samples
processed_data <- tAge_preprocessing(
eset, species = "mouse", split_by = "Tissue",
control_group_column = "Genotype", control_group_label = "WT"
)
#>
#> === Tissue = Kidney (12 samples) ===
#> ✓ Gene filtering completed
#> - Number of genes before filtering: 57010
#> - Number of genes after filtering: 19374
#> - Percentage of genes retained: 34 %
#> ✓ Gene identifiers: Ensembl (15818 of 19374 row names found in the mouse gene table)
#> calcNormFactors has been renamed to normLibSizes
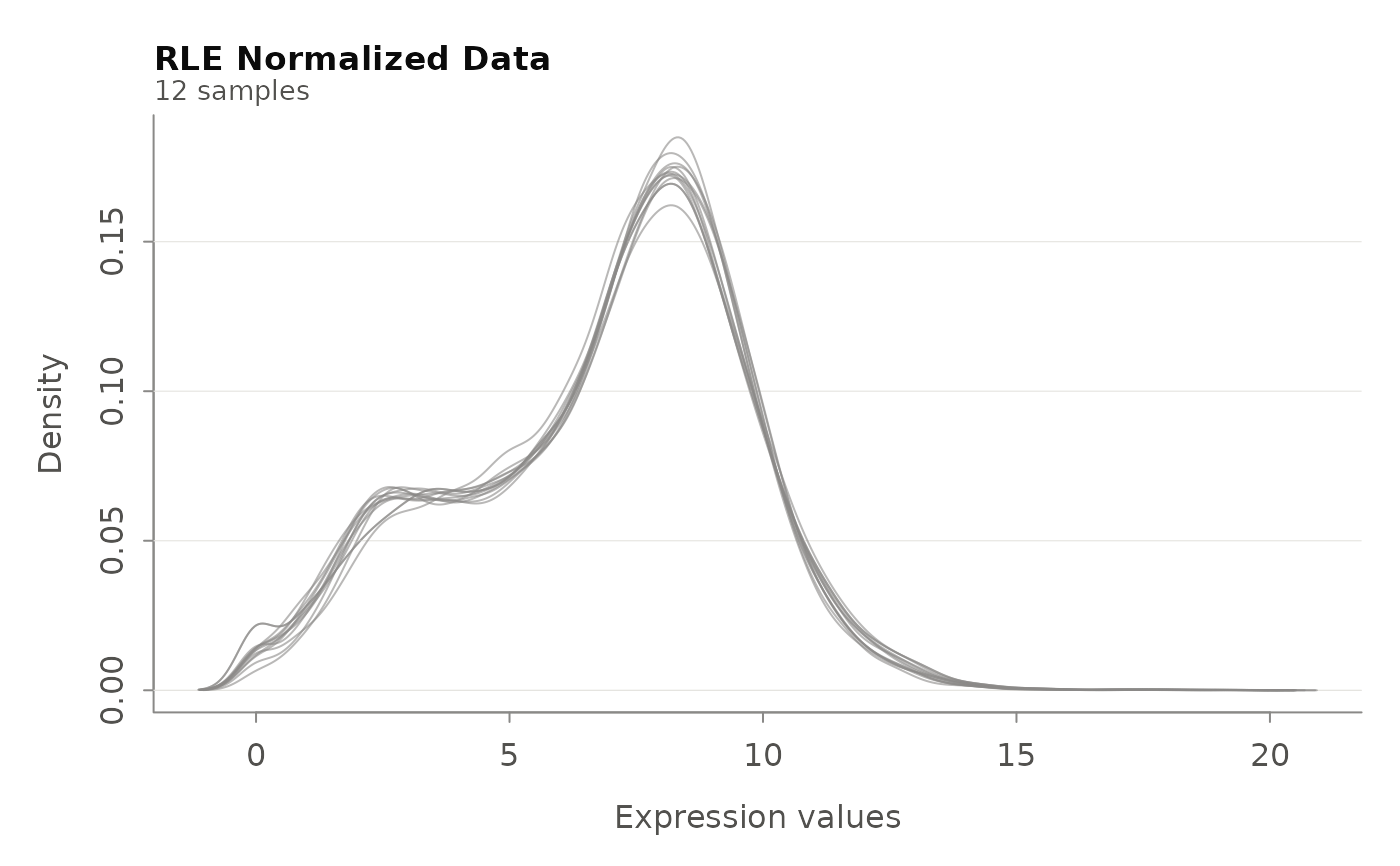
#> ✓ RLE normalization completed
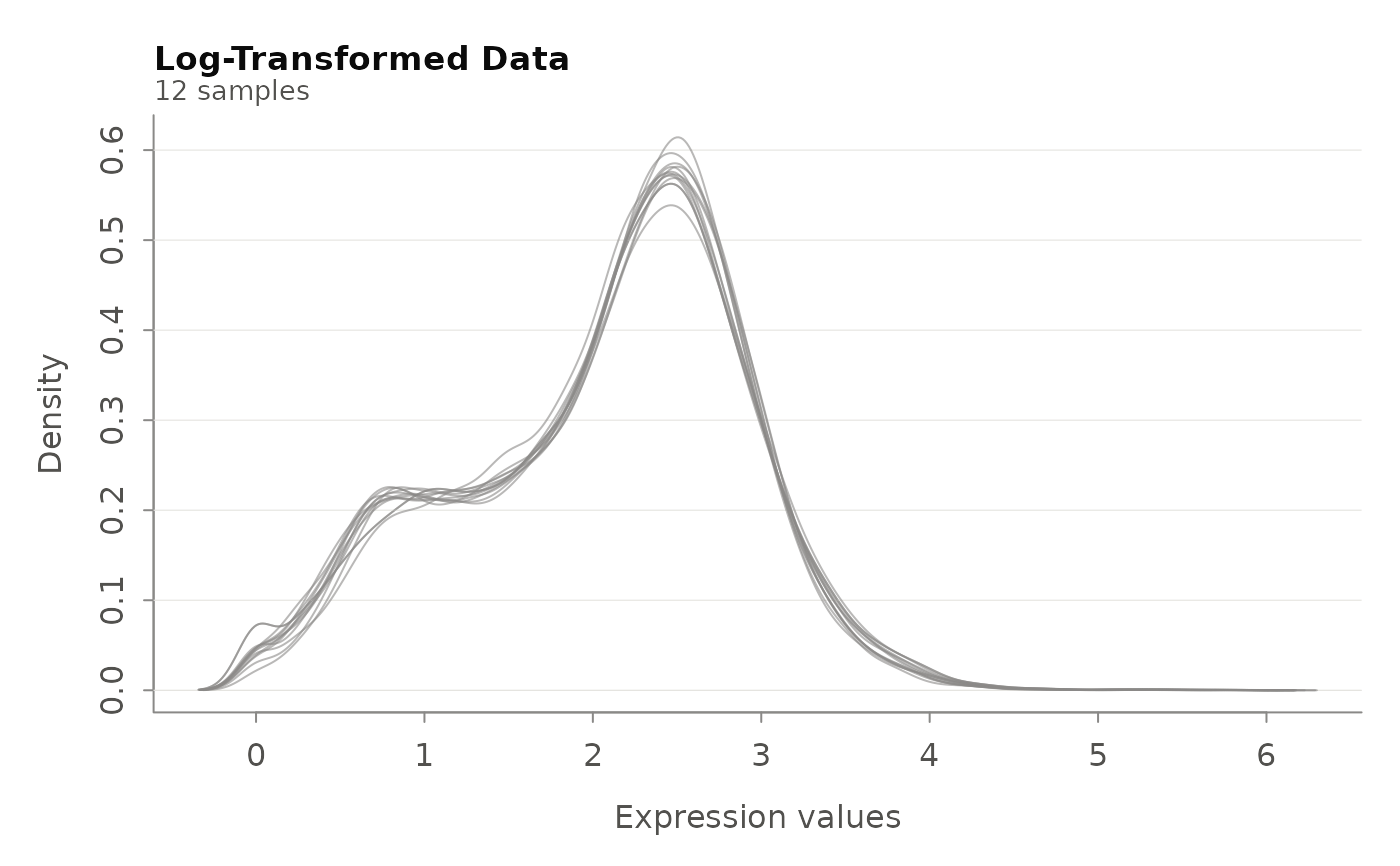
 #> ✓ Log transformation completed
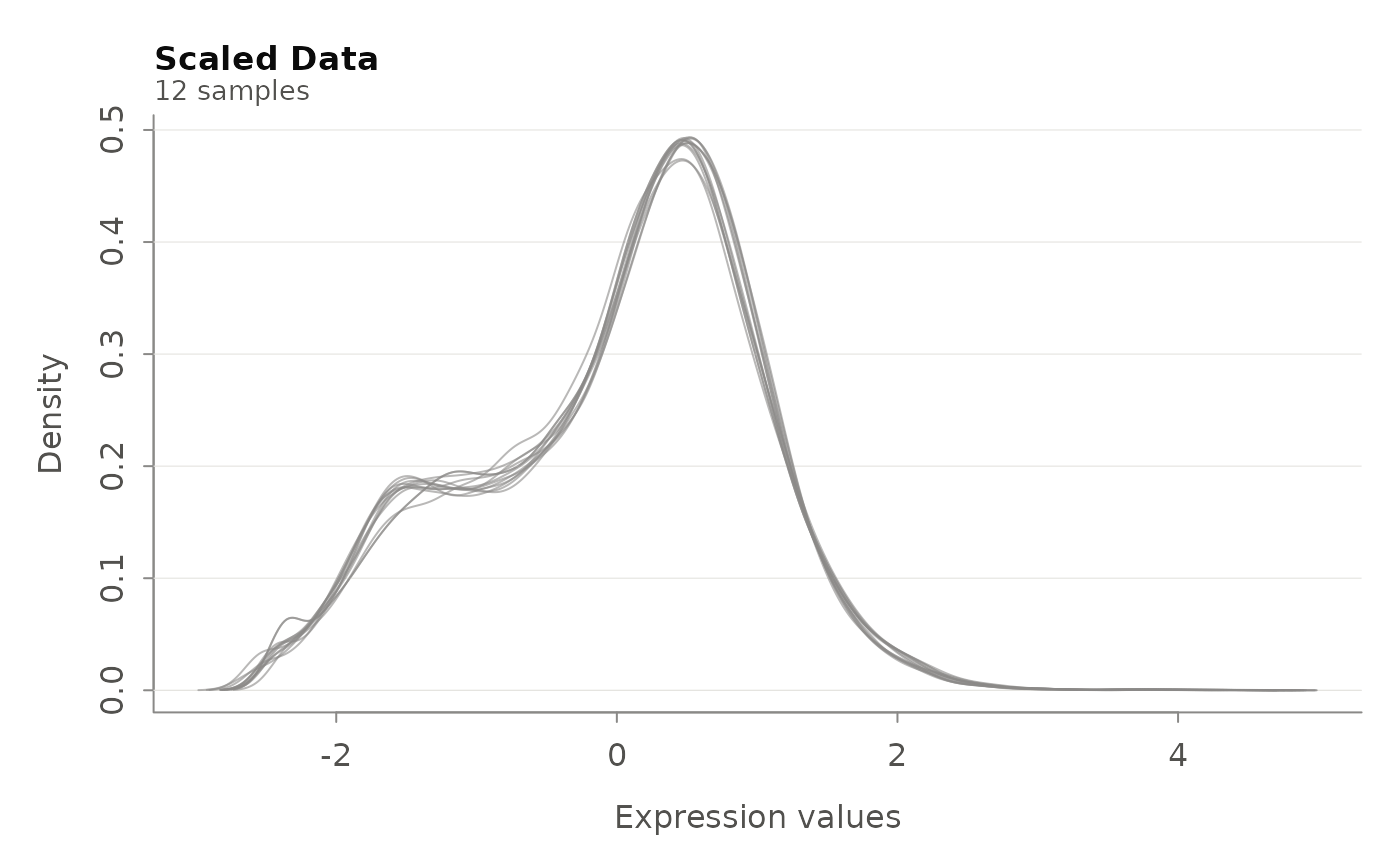
 #> ✓ Scaling completed
 #> ✓ YuGene normalization completed
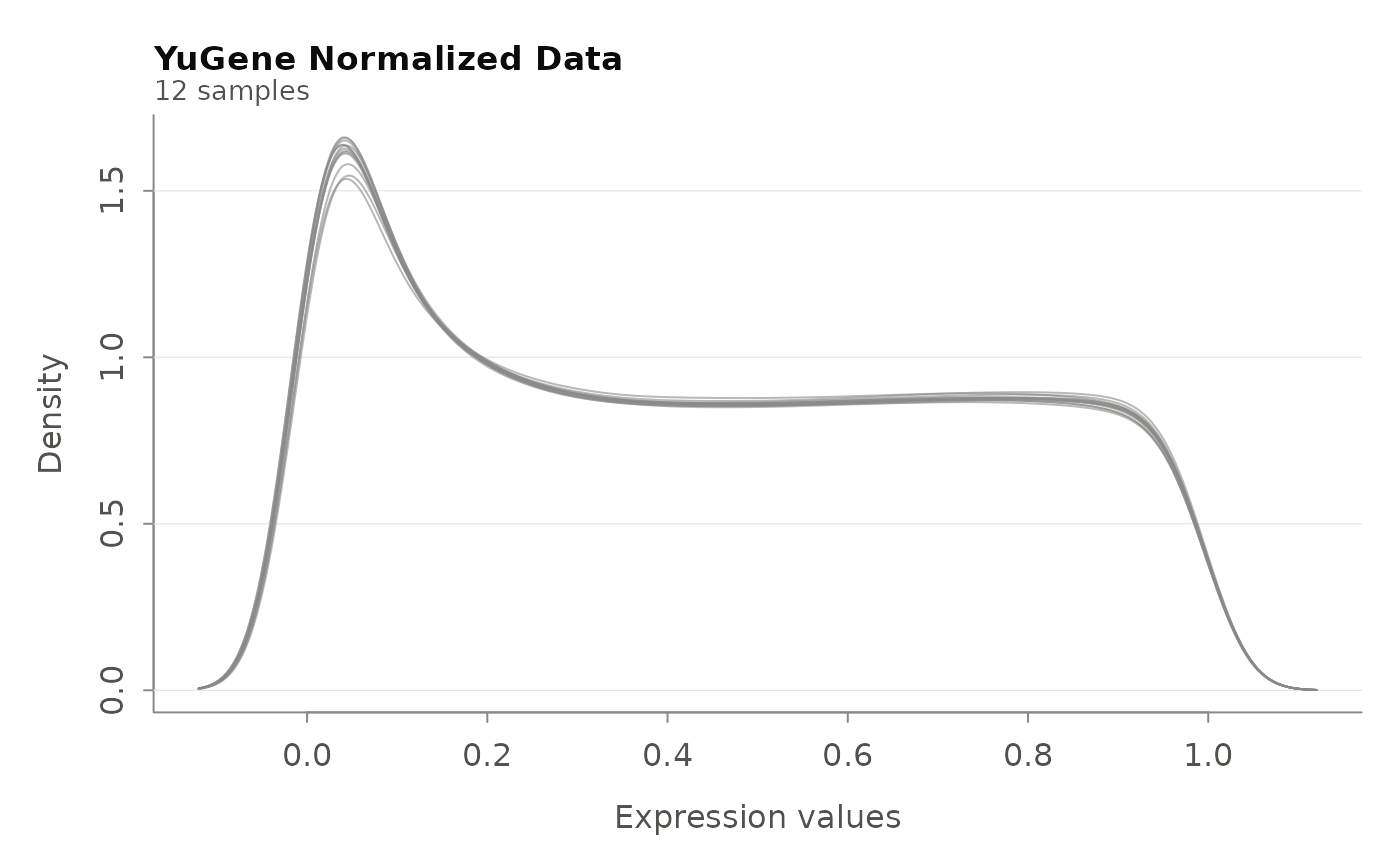 #> ✓ Control samples found for label 'WT'. Using control group median for subtraction.
#> Warning: NaNs produced
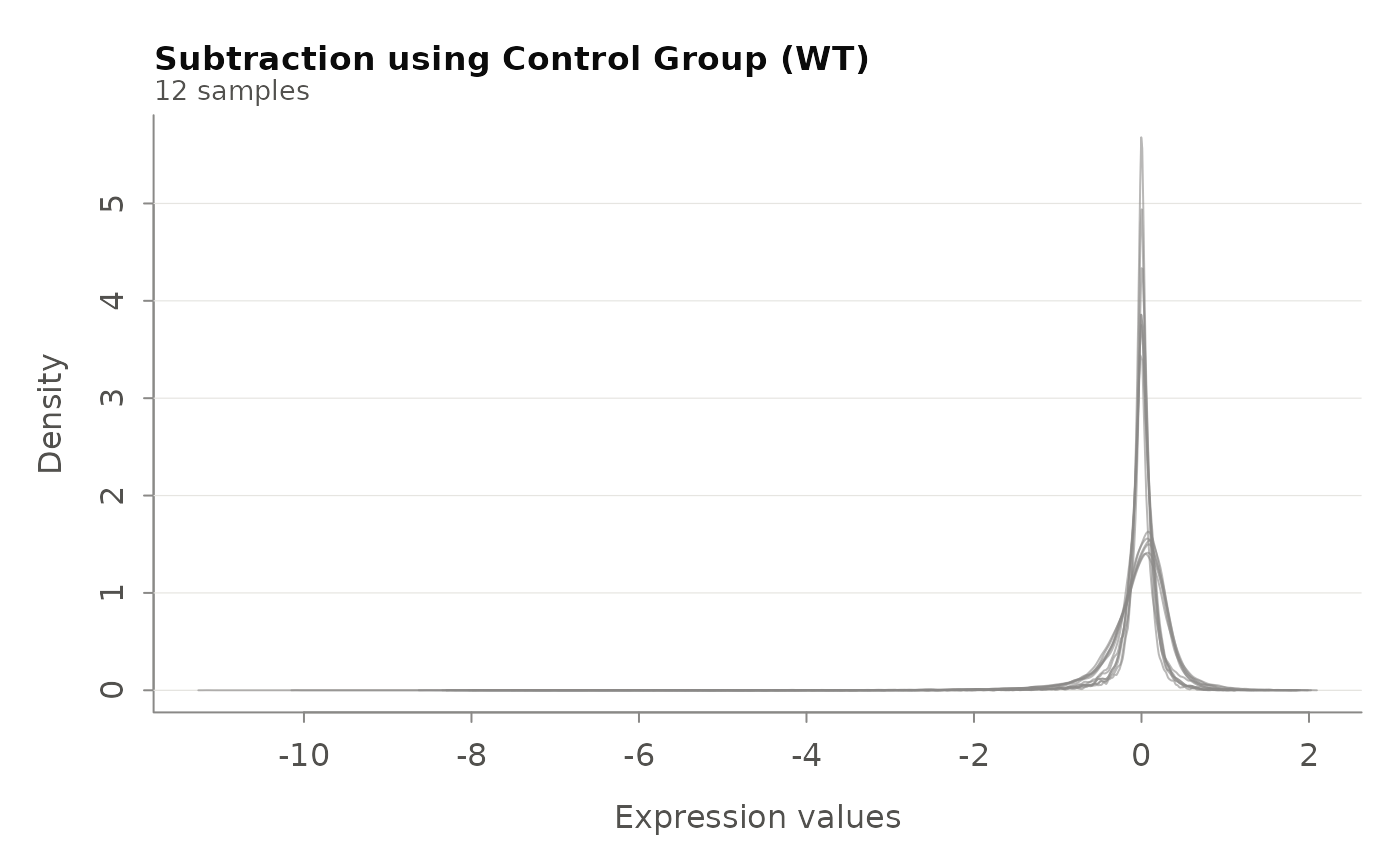 #> ✓ Control samples found for label 'WT'. Using control group median for subtraction.
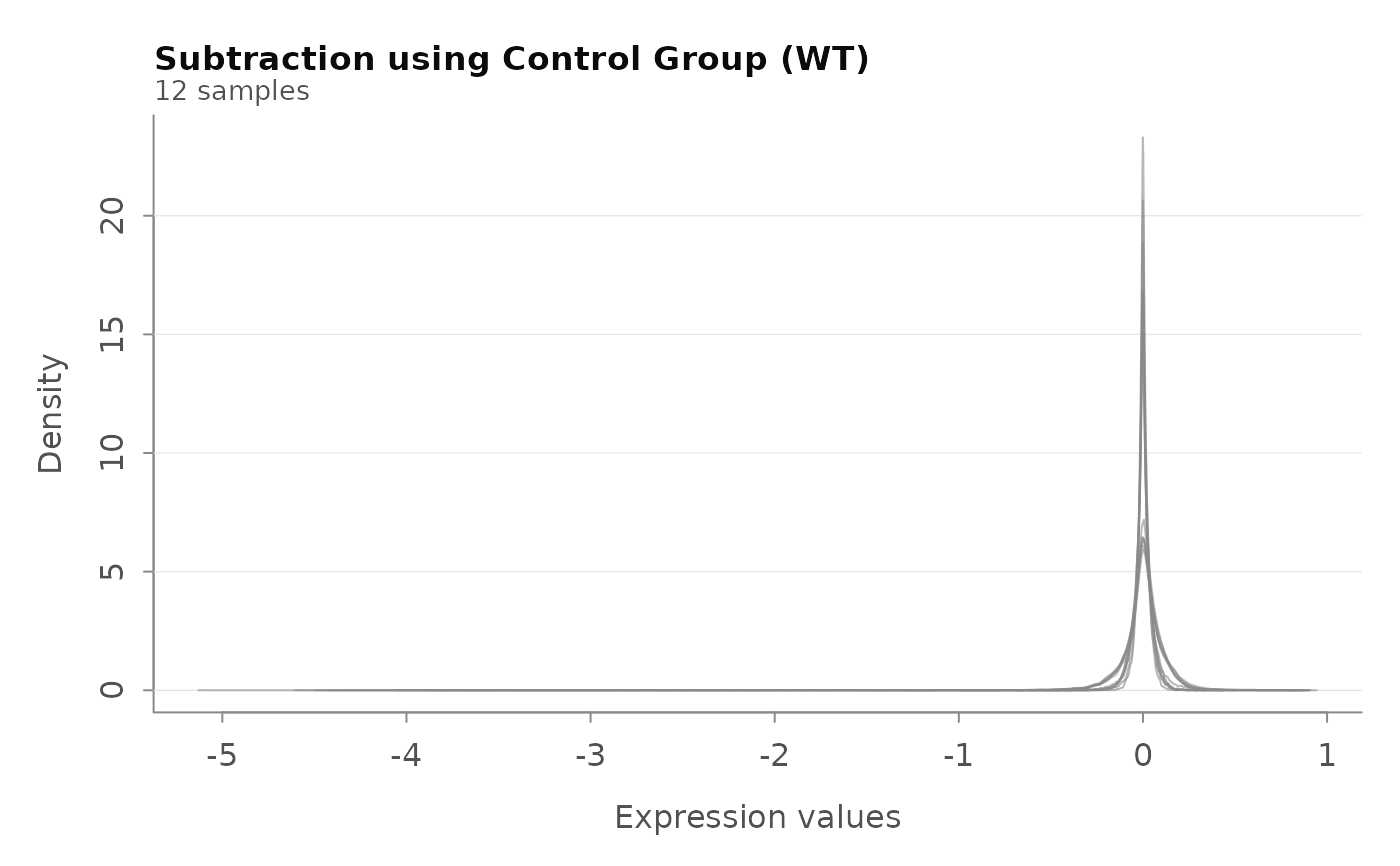 #>
#> === Tissue = Skeletal muscle (12 samples) ===
#> ✓ Gene filtering completed
#> - Number of genes before filtering: 57010
#> - Number of genes after filtering: 16423
#> - Percentage of genes retained: 28.8 %
#> ✓ Gene identifiers: Ensembl (14100 of 16423 row names found in the mouse gene table)
#> calcNormFactors has been renamed to normLibSizes
#> ✓ RLE normalization completed
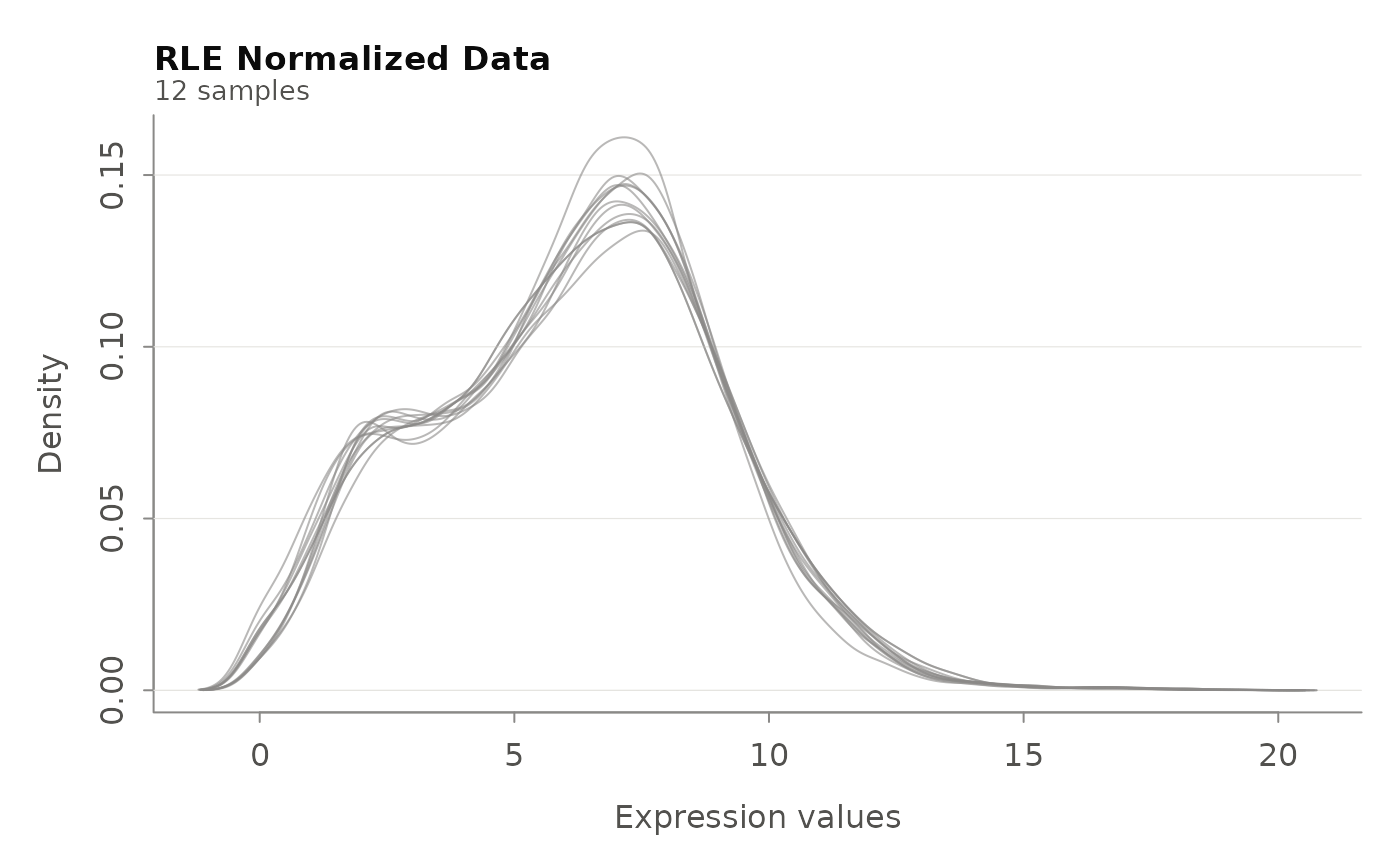 #> ✓ Log transformation completed
 #> ✓ Scaling completed
 #> ✓ YuGene normalization completed
 #> ✓ Control samples found for label 'WT'. Using control group median for subtraction.
#> Warning: NaNs produced
 #> ✓ Control samples found for label 'WT'. Using control group median for subtraction.